
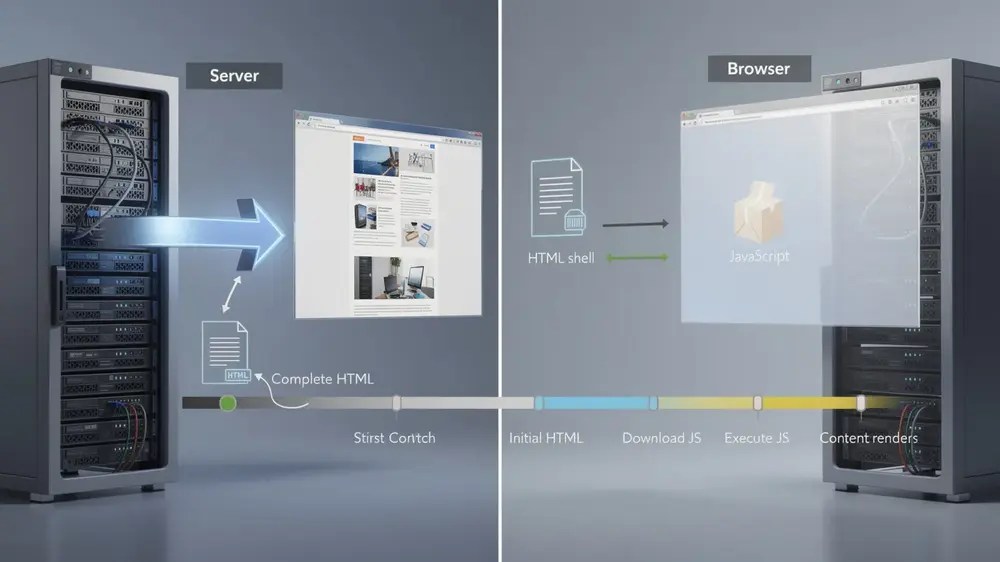
Server-side rendering and client-side rendering describe where a web page’s HTML is assembled. With server-side rendering, the server returns HTML that can already contain the main content and links. With client-side rendering, the browser commonly builds or updates the visible page after JavaScript runs.
Neither method guarantees stronger rankings. Google can render JavaScript, but client-rendered pages introduce dependencies that technical and SEO teams need to test, including script access, API responses, internal links, metadata, and content that appears only after an interaction. Server-side rendering can reduce some of those dependencies, although it may introduce server costs, caching challenges, hydration work, and slower response times when implemented poorly.
The practical question is therefore not whether SSR is always better than CSR. It is whether the chosen architecture allows users and search engines to access the right content, links, and page signals consistently.
- Google can render JavaScript, so client-side rendering is not automatically an SEO problem. The risk comes from implementation failures and additional processing dependencies.
- Server-side rendering can place core content and crawlable links in the initial response, making discovery, testing, and debugging more predictable.
- CSR becomes more vulnerable when important content depends on blocked scripts, failed API requests, user interactions, client-only routing, or unavailable resources.
- SSR does not guarantee faster indexing, better Core Web Vitals, or higher rankings. Server response time, caching, hydration, content quality, and site architecture still matter.
- Static generation, SSR, CSR, and hybrid rendering can coexist within the same website. Different templates should be assessed according to their audience and search requirements.
- The correct way to evaluate a rendering setup is to compare the initial HTML, rendered page, metadata, structured data, links, and real-user performance.
Understanding Server-Side Rendering and Client-Side Rendering
When a browser requests a URL, a website can produce the page in several ways. The two methods most commonly compared in technical SEO are server-side rendering (SSR) and client-side rendering (CSR).
With SSR, the server retrieves the required data and generates HTML for the requested page before sending the response. The browser can display that HTML and then run JavaScript to add interactive behaviour. When a JavaScript framework connects its event handlers and application state to server-generated HTML, the process is commonly called hydration.
With CSR, the server may return a relatively small HTML document containing scripts and an application container. JavaScript then runs in the browser, requests data, and constructs or updates the page. The initial source can therefore contain less meaningful content than the version eventually displayed to the user.
This distinction affects search processing because Google generally crawls a URL, retrieves its resources, and renders JavaScript before using the rendered result for indexing. Google can process many client-rendered pages successfully, but JavaScript adds more points at which the result can differ from what users expect. A blocked script, slow API, browser error, conditional request, or missing route can leave the rendered page incomplete.
The wider discipline of JavaScript SEO and dynamic content processing addresses these risks. It is not concerned with removing JavaScript from modern websites. Its purpose is to ensure that JavaScript does not prevent search engines, accessibility tools, or users on constrained devices from reaching essential information.
Rendering architecture should therefore be treated as a product, performance, and discoverability decision. A public editorial page has different requirements from an authenticated analytics dashboard. Applying one model across an entire platform for the sake of consistency can create unnecessary technical or commercial compromises.
SSR and CSR Comparison
| Consideration | Server-Side Rendering | Client-Side Rendering |
|---|---|---|
| Initial HTML | Can contain the page’s main content, headings, links, and metadata | May contain an application shell while content is added after JavaScript runs |
| Dependence on rendering | Core content can be available before client-side execution | Important content may depend on successful scripts and data requests |
| Server requirements | May require more server or edge processing for each request | Can serve lightweight static assets while more work occurs in the browser |
| Browser workload | Hydration and interactive components can still require substantial JavaScript | The browser commonly performs more of the initial rendering work |
| Caching | Depends on personalisation, data freshness, and infrastructure design | Static application files can be cached effectively, although data requests remain separate |
| SEO predictability | Core public content is generally easier to inspect in the initial response | Requires careful testing of rendered content, routes, resources, and links |
| Typical use | Public landing pages, editorial content, product pages, and indexable resources | Authenticated applications, internal tools, and highly interactive private interfaces |

How SSR and CSR Affect Crawling and Indexing
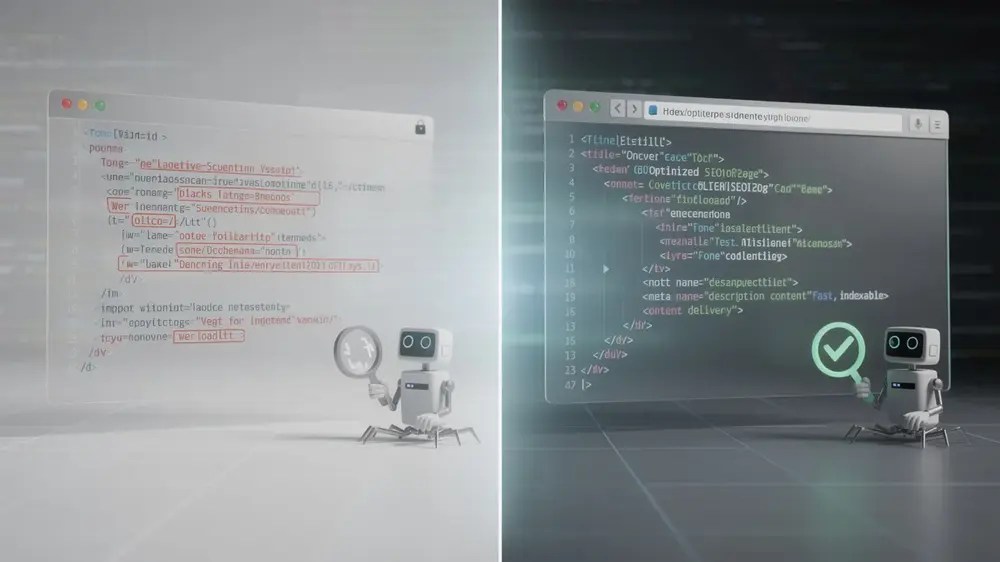
Server-side rendering can make important content and links available in the initial response. This reduces reliance on the rendering stage and makes it easier for developers and SEO teams to inspect what a crawler receives before JavaScript executes.
That advantage should not be described as a guarantee of faster indexing or stronger visibility. Google still decides whether to index a page based on a wider set of signals, including accessibility, duplication, canonicalisation, content usefulness, internal discovery, site quality, and demand. An SSR page with weak content or incorrect directives can perform worse than a well-built CSR page.
CSR presents a different operational profile. Google can execute JavaScript, but the final result depends on the resources and requests required to assemble the page. Problems arise when:
- JavaScript files or API endpoints are blocked or unavailable to crawlers.
- The application returns an empty shell while data requests fail.
- Important text appears only after a click, scroll, or other user action.
- Internal navigation uses event handlers without crawlable
<a href>links. - Routes rely on URL fragments instead of stable indexable URLs.
- Content requires authentication, local storage, location access, or a particular cookie state.
- JavaScript errors prevent the application from completing its render.
- The server returns a successful status for an error page, creating a possible soft 404.
Understanding how crawling, rendering, and indexing work helps teams distinguish an architectural risk from an observed search problem. A page should not be rebuilt simply because its framework uses client-side components. The first step is to confirm whether Google can access the scripts, render the main content, find the links, and interpret the intended page signals.
Other crawlers may behave differently. Social media preview bots, messaging applications, third-party SEO tools, accessibility services, and smaller search engines do not necessarily execute JavaScript in the same way or with the same resources as Google. Public pages that depend on rich previews or international search platforms may therefore benefit from meaningful HTML that is available without full browser execution.
Rendering and Page Experience
Rendering choices can influence loading and interaction performance, but neither SSR nor CSR is inherently fast. SSR can allow meaningful content to appear early, yet slow database requests or uncached server work can weaken time to first byte and Largest Contentful Paint. A page can also display server-rendered content quickly and then become unresponsive while a large JavaScript bundle hydrates.
CSR can serve a lightweight shell quickly, but that shell provides limited value if users must wait for scripts and API responses before they can read or interact with the main content. The relevant outcome is the experience delivered to real users, not the architectural label.
For search and user experience reviews, monitor the current Core Web Vitals:
- Largest Contentful Paint (LCP): how quickly the main visible content loads
- Interaction to Next Paint (INP): how responsive the page is to user interactions
- Cumulative Layout Shift (CLS): how visually stable the page remains while loading
Good Core Web Vitals can support a stronger page experience, but they do not guarantee high rankings. Field data, template-level testing, content quality, and the wider user journey should be reviewed together.

Selecting the Right Rendering Approach
The appropriate rendering method follows from the purpose of each page. Teams should assess whether the URL needs organic discovery, how frequently its content changes, whether it is personalised, what level of interaction it requires, and which technical resources are available to operate it reliably.
Consider SSR or Static Rendering When
- The page is public and organic search is an important discovery channel.
- The main content, internal links, and page signals should be available in the initial response.
- Social sharing previews and non-browser clients need dependable metadata.
- The content is stable enough to benefit from caching or pre-generation.
- The team wants rendering failures to be easier to detect through raw HTML checks.
Static generation may be a better option than request-time SSR for content that changes infrequently. It produces HTML before the user requests the page and can often be served efficiently through a content delivery network. Some frameworks also support incremental regeneration, which updates static pages without requiring a complete site rebuild.
Consider CSR When
- The area sits behind authentication and is not intended for search indexing.
- The experience depends heavily on application state and real-time interaction.
- Public acquisition pages are handled separately through static or server rendering.
- The content is user-specific and has little value outside the active session.
- The team has tested deep links, accessibility, error handling, and non-browser clients.
Dashboards, account management tools, reporting interfaces, and internal administration systems often fit this profile. Using SSR for every private interaction may add operational complexity without creating a meaningful search benefit.
Consider a Hybrid Architecture When
- Public landing pages require crawlable HTML while the product itself needs rich client-side interaction.
- Different templates have different search, personalisation, and performance requirements.
- Stable resources can be generated statically while dynamic routes use SSR or CSR.
- Interactive components can be added to server-rendered pages without moving the entire page to CSR.
Modern frameworks increasingly encourage this component-level approach. Static content and search-facing elements can be produced on the server, while selected client components handle state, browser APIs, and user interaction. The result is not always a simple SSR or CSR classification, which is why pages should be tested according to their final output rather than their framework configuration alone.
Metadata deserves particular attention. Where practical, provide stable titles, robots directives, canonical signals, and social metadata in the initial HTML. Google can process JavaScript-generated elements, but this introduces an additional dependency. Teams should confirm that every important template produces the intended metadata after rendering and that server and client values do not conflict.
A broader technical SEO audit can help identify template-level differences between initial and rendered output, particularly across large sites where manually checking every URL is unrealistic.
The practical rule is not “use SSR whenever SEO matters”. A more useful rule is: make public content, links, and page signals consistently accessible, then choose the least complex rendering model that meets the product’s performance, personalisation, and operational requirements.
Common Misconceptions About Rendering and SEO
Google Cannot Index Client-Rendered Content
This is inaccurate. Google can render JavaScript and index content produced in the browser. The more precise concern is that CSR introduces dependencies that can fail or produce a different result for crawlers. A client-rendered page should be tested, not rejected automatically.
SSR Automatically Improves Rankings
SSR can simplify access to content and links, but it does not improve relevance, authority, originality, or user satisfaction by itself. It also cannot correct poor site architecture, duplicate pages, weak internal linking, incorrect canonical tags, or unhelpful content. Rendering is one part of a wider technical SEO framework, not a ranking shortcut.
SSR Is Always Faster
An SSR page may display meaningful content quickly, but it can also be delayed by slow server processing, uncached requests, data waterfalls, regional latency, or overloaded infrastructure. Hydration can then add further browser work after the HTML appears.
A CSR application may feel fast after its resources have been cached, especially when users navigate between private application views. Performance should be measured across first visits, repeat visits, devices, network conditions, and geographical markets rather than inferred from the rendering model.
JavaScript-Generated Metadata Is Always Ignored
Google can process metadata and structured data produced through JavaScript. However, dynamic generation adds another point of failure and can create conflicts between the original response and the rendered document.
For important templates, confirm that:
- Each indexable URL has a distinct and relevant title.
- Robots directives do not change unexpectedly after rendering.
- The canonical URL is stable and points to an indexable destination.
- Structured data describes content visible to users.
- Open Graph and other sharing metadata work for services that do not render JavaScript.
- Error states do not inherit the metadata of a successful page.
Prerendering Always Solves the Problem
The term “prerendering” is used for several different approaches, including static generation, server rendering, and bot-specific dynamic rendering. These should not be treated as interchangeable.
Google describes dynamic rendering, where bots receive a different server-rendered version from users, as a workaround rather than a recommended long-term solution. It creates additional infrastructure and makes it easier for the two versions to drift apart. Static generation, SSR, or a hybrid architecture that provides equivalent content to users and search engines is generally easier to maintain.
Every Public Page Needs the Same Architecture
A news article, ecommerce product page, campaign landing page, pricing calculator, and account dashboard can all belong to the same domain while requiring different rendering strategies. Template-level decisions are often more practical than a site-wide rule.
Rendering debates become unhelpful when the framework label replaces evidence. The useful comparison is between what the server returns, what the browser builds, what a crawler can access, and what the user ultimately experiences.

Implementation Best Practices for SEO-Friendly Rendering
The quality of the implementation matters more than the name of the rendering method. A carefully tested CSR application can be accessible to Google, while an SSR deployment can still fail because of incorrect status codes, unavailable data, conflicting metadata, or hydration errors.
Keep Essential Content Accessible
Public pages should not require a click, scroll, tab selection, or form submission before their primary content becomes available. Lazy loading can be useful for secondary assets and below-the-fold elements, but the main answer and essential links should not depend on user interaction.
Use Crawlable Internal Links
Search-facing navigation should use standard HTML links with valid destinations. Buttons and JavaScript event handlers may support application behaviour, but they should not be the only mechanism through which crawlers can reach important URLs.
Client-side routing should also update the browser history and create stable URLs that can be opened directly. A route that works only after navigating from the homepage may fail for users, crawlers, and shared links.
Return Accurate HTTP Status Codes
Single-page applications sometimes return a successful 200 response for every path, including missing pages. If the rendered document displays an error while the server still reports success, search engines may interpret the result as a soft 404.
Missing content should produce an appropriate 404 or 410 response. Permanent redirects should return a server-side redirect status rather than relying only on client-side navigation after the page loads.
Make Resources Available to Crawlers
Check that robots.txt and security controls do not block scripts, stylesheets, images, or API requests needed to render the page. A resource that works for a logged-in developer may still fail for Googlebot because it requires credentials, headers, location data, or a particular session state.
Plan for API and JavaScript Failure
Applications should provide useful error handling when data cannot be retrieved. An empty page with an indefinite loading indicator gives users and crawlers little information. Where possible, return meaningful server content or a clear status rather than leaving the page dependent on a request that may never complete.
Keep Server and Client Output Consistent
Hydration mismatches occur when the HTML generated by the server differs from what the client expects. They can cause visual changes, lost content, duplicate elements, or JavaScript errors. Test templates with personalisation, dates, language settings, consent controls, and experiments, since these frequently produce different server and browser states.
Measure Performance in Real Conditions
Rendering decisions connect closely to page speed optimisation, but laboratory results alone are not enough. Review field data across devices and markets, particularly when a global site serves users far from its origin infrastructure.
A server-rendered page may perform well in the United Kingdom but respond slowly in Japan if data and compute remain concentrated in Europe. Edge caching or regional infrastructure may help, although personalisation and rapidly changing data can limit what can be cached. Performance architecture should account for actual audience geography rather than relying on one local test.
How to Test SSR and CSR Pages for SEO
A rendering decision should be verified with output, not assumptions. Testing one representative URL is useful during development, but production reviews should include every important template, language, device configuration, and content state.
1. Inspect the Initial HTML Response
Use View Source, an HTTP client, or a crawler that does not execute JavaScript. Check whether the response contains the main heading, essential copy, internal links, title, canonical tag, robots directives, and any critical structured data.
The initial source does not need to contain every interactive detail, but it should help the team understand which elements depend on rendering.
2. Compare the Rendered DOM
Open the page in browser developer tools and inspect the DOM after JavaScript has completed. Compare it with the initial source and look for:
- Content added, removed, or replaced after rendering
- Headings or links that appear only after interaction
- Duplicate metadata or conflicting canonical tags
- Loading states that never resolve
- JavaScript errors and failed network requests
- Unexpected redirects or route changes
3. Test Without JavaScript
Disabling JavaScript is not a simulation of Googlebot, since Google can execute scripts. It is still a useful diagnostic step because it reveals which parts of the page depend completely on client execution.
For a public page, ask whether the remaining HTML communicates the page’s purpose and exposes its important links. A blank shell does not automatically mean the URL cannot be indexed, but it indicates greater reliance on successful rendering.
4. Use Google Search Console
Use the Google Search Console URL Inspection tool to test a live URL and examine Google’s rendered view. Confirm that the visible content, screenshots, status, canonical signals, and loaded resources match the intended page.
A successful live test does not prove that every URL or every future crawl will behave identically. It does, however, provide direct evidence for the tested page and can reveal blocked resources, rendering failures, and unexpected page states.
5. Validate Links and Structured Data
Check that important links exist as crawlable HTML anchors in the final output. Validate structured data using Google’s supported testing tools and confirm that the marked-up information is visible to users.
Where structured data is generated through JavaScript, test the rendered page rather than assuming that a script has executed correctly.
6. Crawl Representative Templates
A site-wide JavaScript crawl can identify differences that a single URL check will miss. Compare non-rendered and rendered crawl results for:
- Page titles and descriptions
- Canonical URLs
- Robots directives
- Headings and word counts
- Internal links
- Status codes and redirects
- Structured data
- Images and alternate-language references
7. Review Server Logs and Monitoring
Server logs can show whether Googlebot reaches important routes, receives errors, or repeatedly requests resources required for rendering. Application monitoring can reveal API failures and JavaScript exceptions that may not appear during a manual test.
8. Test International and Localised Pages Separately
Global websites should not assume that one language version represents every market. Regional APIs, consent systems, currency selectors, translation layers, and geolocation redirects can change the rendered result.
Test direct access to Korean, Japanese, and European market URLs without relying on a previous session. Confirm that Googlebot is not redirected according to an assumed location and that each version returns the intended language, metadata, canonical signals, and alternate-language references.
9. Recheck After Releases
Rendering issues often appear after framework upgrades, routing changes, consent-platform deployments, analytics updates, or component refactoring. Add representative SEO checks to the release process rather than waiting for a fall in traffic to expose a template problem.
The objective is not to prove that SSR or CSR is universally superior. It is to establish that the chosen implementation provides consistent content, links, metadata, status codes, and performance for the audiences and crawlers that matter to the site.
For most organisations, the strongest rendering strategy is the one that reflects the real structure of the product. Public acquisition pages may benefit from static or server-generated HTML, while private application areas can retain client-side interaction. The final choice should be supported by testing, performance data, maintenance capacity, and a clear understanding of how each template contributes to the user journey.
- Google Search Central: JavaScript SEO basics
- Google Search Central: Fix search-related JavaScript problems
- Google Search Central: Dynamic rendering as a workaround
- Google Search Central: Link best practices and crawlable links
- Google Search Central: Core Web Vitals and search results
- Google Search Central: Generating structured data with JavaScript
- web.dev: Rendering on the Web
- Next.js: Rendering strategies
- Next.js: Client-side rendering


