
JavaScript SEO is the part of technical SEO that checks whether search engines can discover a URL, render the page state they need and index the content you intend to expose. JavaScript itself is not an SEO problem. Google Search runs JavaScript with an evergreen version of Chromium and uses rendered HTML when processing JavaScript pages.
The useful question is therefore not whether a site uses JavaScript. It is what the page depends on JavaScript to produce. If the main content, navigation, metadata or routing disappears when a script, resource or API request fails, that dependency deserves an SEO check. A page can look complete in an ordinary browser session while still giving a crawler a materially different result.
Start With What Depends on JavaScript
A framework name tells you very little on its own. A client-rendered page can be indexable, while a server-rendered page can still fail because of a bad canonical, blocked resource or broken internal route. Start by identifying which search-critical elements depend on JavaScript and how Google receives them.

| Page element | JavaScript can be used? | What to verify |
|---|---|---|
| Main content | Yes | Confirm the important text appears in the rendered HTML without requiring a user action. |
| Internal links | Yes | Links inserted into the DOM should still use standard <a href="..."> markup with a resolvable URL. |
| Title and meta description | Yes | Google can process JavaScript changes, but the final rendered values should be stable and relevant to the page. |
| Canonical URL | With care | Google recommends HTML as the best place for a canonical. If JavaScript sets it, avoid conflicting values between the initial and rendered page. |
| Structured data | Yes | Google can process JavaScript-generated JSON-LD when it is available in the rendered DOM. Test the actual implementation. |
| Lazy-loaded content | Yes | Do not make important content depend on a click, swipe or other interaction that Google Search does not perform. |
This distinction matters because JavaScript SEO is not a rule that all critical content must be present in the initial HTML. Server-rendered HTML reduces dependencies, but Google can process client-rendered content when the implementation produces a usable rendered page. Google’s JavaScript SEO documentation describes that process directly.
How Google Processes a JavaScript Page
Google describes three main phases for JavaScript web apps: crawling, rendering and indexing. During the first fetch, Googlebot can parse the HTML response and extract URLs from crawlable links. Pages that are eligible for processing can then enter the rendering queue, where Google’s Web Rendering Service executes JavaScript and produces rendered HTML. That rendered result is used for further link extraction and indexing.
The broader crawling and indexing guide explains the full search-processing sequence. For JavaScript SEO, one distinction deserves particular attention: the initial source and the rendered HTML are not the same evidence.
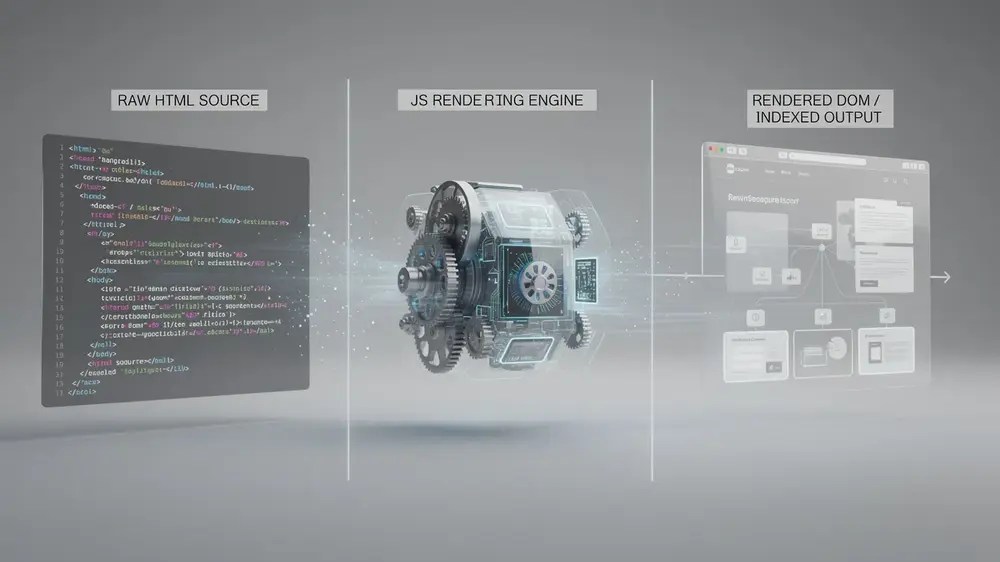
Source HTML and Rendered HTML Answer Different Questions
View Source shows what the server returned before client-side scripts changed the page. The live DOM in a browser shows the page after scripts have run in that session. Google’s rendered HTML shows what its renderer produced under Google’s crawling and rendering conditions.
A thin initial response is not automatically an indexing problem if the rendered HTML contains the intended content and links. The reverse is also true. A normal browser can have stored state, cookies or resources that make a page appear healthy even when Googlebot encounters an error, blocked file or different response. Diagnosis should compare outputs rather than infer the answer from the framework.
Choose a Rendering Approach by Failure Cost
Client-side rendering, server-side rendering, static rendering and hydration can all appear in searchable websites. The choice is not an SEO contest with one universal winner. It depends on how much of the page relies on rendering, how quickly the content changes, what other crawlers need to access it and how much complexity the development team can maintain.
Client-Side Rendering Can Work
Client-side rendering can be suitable when each important view has a stable URL, the main content and crawlable links appear in the rendered HTML, required resources are accessible, and the page does not depend on a logged-in session or user interaction to reveal what should be indexed.
The drawback is dependency. More of the page’s searchable state relies on successful JavaScript execution and supporting requests. That does not make client-side rendering inherently bad for Google Search, but it gives the team more conditions to verify.

Server-Side or Static Output Reduces Rendering Dependency
Google still describes server-side and pre-rendering as useful approaches because they can make content available sooner for users and crawlers, including bots that do not execute JavaScript. Static rendering, server-side rendering or a hybrid approach can be a sensible choice when the page’s main content, product information or internal routes are too important to leave entirely to client execution.
Dynamic rendering, where bots receive a separately rendered version, is different. Google describes it as a workaround rather than a recommended long-term solution and points developers towards server-side rendering, static rendering or hydration instead. That guidance is worth considering before adding a crawler-specific rendering layer that creates another version of the page to maintain.
Make URLs and Page Signals Survive the Render
Use Crawlable Links and Stable URLs
Google generally crawls links when they are HTML <a> elements with an href attribute. JavaScript may create those links in the DOM, but a click handler on a button or a link without a usable href is not an equivalent discovery path. If a page matters, give it a real URL and connect it through crawlable internal links. MOCOBIN’s internal linking guide covers the wider site-architecture side of that decision.

Single-page applications need the same discipline. Google recommends using the History API for routing between distinct views rather than relying on URL fragments to load different page content. Each piece of content that should be independently discoverable needs a persistent URL that Google can resolve.
Treat Canonicals, Robots Rules and Structured Data Separately
JavaScript can change a title or meta description, and Google can process an injected canonical during rendering. Canonicals need more caution than ordinary metadata because conflicting values can produce unexpected canonicalisation. Google’s preferred approach is to set the canonical in HTML; if JavaScript must set it, do not leave a different canonical in the original HTML.
Structured data is another common source of unnecessary rules. Google can understand JSON-LD generated with JavaScript when it is present in the rendered DOM. It does not have to be server-generated simply to be eligible for processing. The implementation still needs to match the visible page and the relevant Google feature requirements, which is why the schema markup guide separates valid vocabulary from current Google support.
Do Not Hide Important Content Behind Interaction
Lazy-loading can improve performance, but Google Search does not click, swipe or scroll the page as a user would. Important content should load when it becomes visible in the viewport rather than only after an interaction. JavaScript and CSS resources needed to produce that content also need to remain accessible to Googlebot.
Diagnose JavaScript SEO With Rendered Evidence
Rendering should be investigated when there is evidence that it may be the failing layer, not used as the default explanation for every indexing problem. A useful diagnostic sequence is:
- Confirm the URL can be processed. Check the HTTP response, robots.txt access, robots meta directives and intended canonical before blaming JavaScript.
- Compare the initial response with the rendered result. Look for the main content, headings, internal links, title, canonical and any search-critical data that JavaScript is expected to add.
- Inspect failed resources and script errors. A missing API response, blocked JavaScript file or runtime exception can leave the rendered page incomplete even when the interface works in another browser session.
- Check whether content depends on interaction or stored state. Logged-in data, local storage, consent state and click-triggered content can produce a different page for a crawler.
- Test representative templates. One successful URL does not prove that every product, category or article template renders the same way.

Google recommends the URL Inspection Tool in Search Console or the Rich Results Test when you need to see rendered output, loaded resources and JavaScript errors. These checks are most useful when a rendered page is missing content or important page signals.
A complete browser view is not proof that Google received the same result. Equally, a sparse View Source is not proof that a JavaScript page cannot be indexed. The rendered evidence decides which of those two concerns is real.
Fix JavaScript SEO Problems in Dependency Order
Teams often start with bundle size because JavaScript and performance are easy to associate. That can be useful, but it is not always the first SEO problem to solve. A page that returns the wrong status code or hides its main links behind an interaction needs a different first fix.
| Priority | Check | Why it comes here |
|---|---|---|
| 1 | Access, status codes and index directives | If Google cannot fetch or is told not to index the URL, later rendering work cannot solve the basic state. |
| 2 | Stable URLs and crawlable links | Important views need discoverable routes before deeper rendering analysis has much value. |
| 3 | Rendered main content and metadata | Confirm that the page Google can render still contains the information and signals that define its purpose. |
| 4 | Interaction, API and resource dependencies | Fix conditions that make the rendered result incomplete or inconsistent. |
| 5 | Performance and responsiveness | Reduce unnecessary JavaScript work and address real user experience problems after access and rendering are sound. |
| 6 | Search enhancements | Validate structured data and other enhancements after the underlying page is reliable. |
JavaScript can contribute to poor performance through long main-thread tasks, render-blocking work and heavy third-party scripts. Google’s current Core Web Vitals are Largest Contentful Paint (LCP), Interaction to Next Paint (INP) and Cumulative Layout Shift (CLS). Google says Core Web Vitals are used by its ranking systems, but good scores do not guarantee high rankings. For implementation work, use the Core Web Vitals and speed optimisation guide rather than treating JavaScript SEO as a substitute for a performance audit.

The durable standard is not ‘no JavaScript’. It is a site with resolvable URLs, crawlable links and a rendered page that contains the content and signals needed to understand what each URL is for. When those conditions hold, JavaScript is an implementation choice rather than an indexing theory.


